What Is LMArena AI?
LMArena AI was a platform for comparing different AI models through real user interactions. It was created by researchers from UC Berkeley to measure how AI performs in real-world tasks. Users could compare two model responses and vote for the better one. In January 2026, LMArena officially became Arena and expanded beyond language models. Today, the platform covers areas such as text, coding, vision, search, documents, images, and video.
How LMArena AI Works
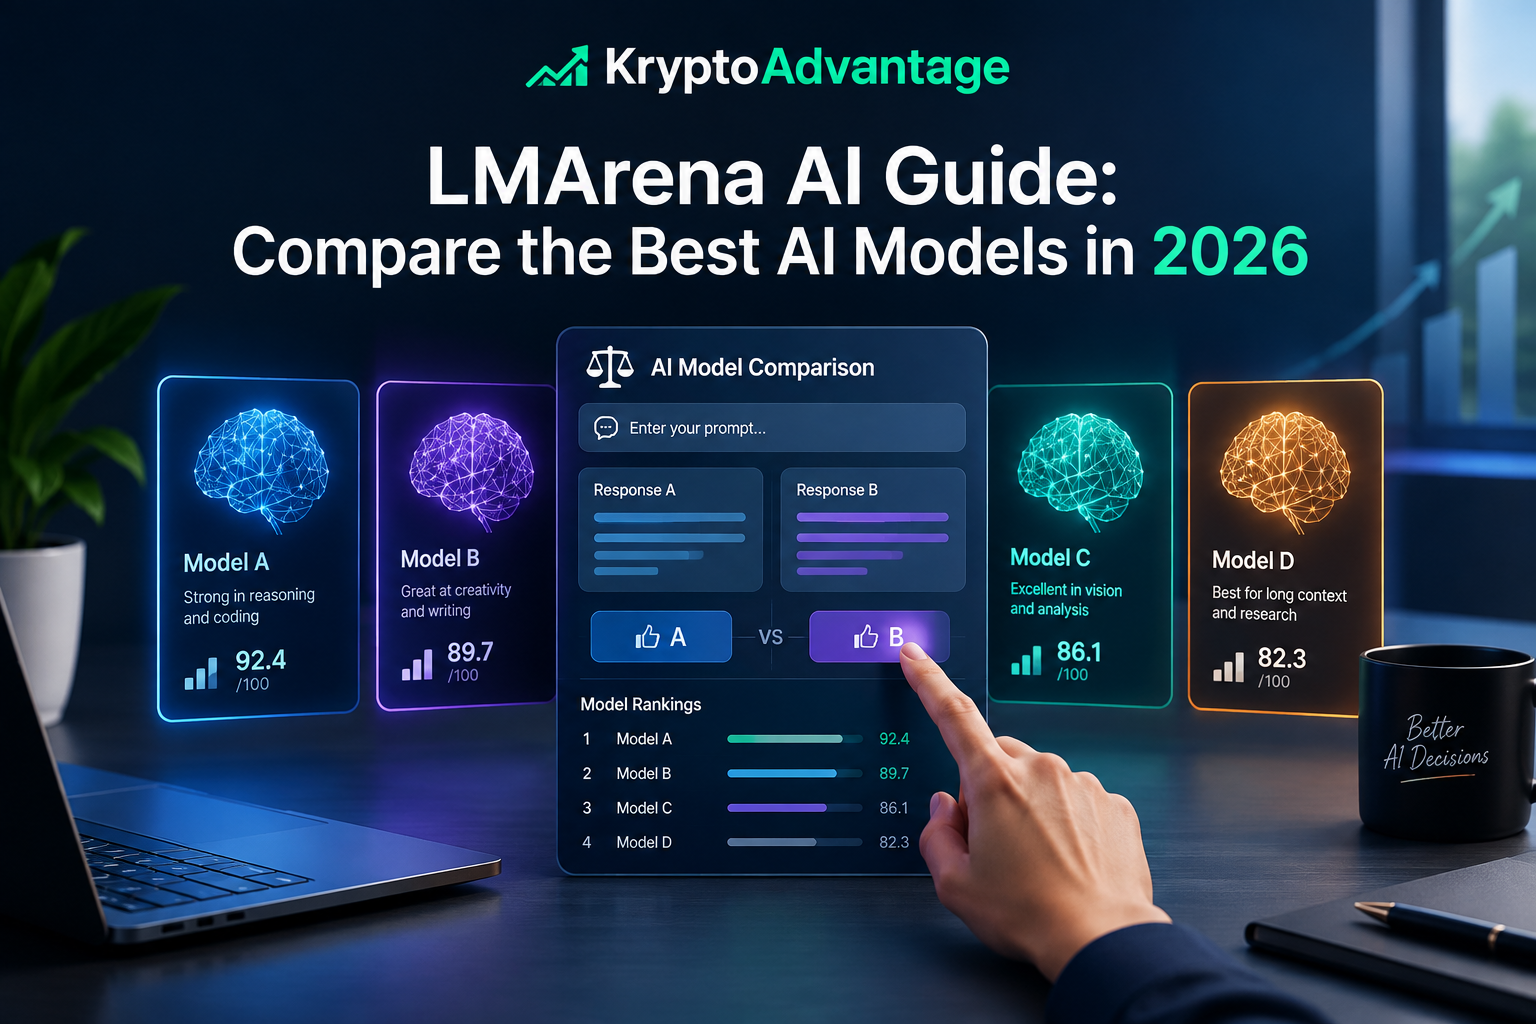
Users enter a prompt and choose the right AI tool for their task. In Battle Mode, two anonymous models generate responses. Users compare both answers and vote for their preferred response. The model names appear only after the vote is submitted. These votes help calculate model ratings and update public leaderboards. Arena uses the Bradley-Terry rating system for these rankings.
How Does LMArena AI Rank Models?
Arena ranks models using votes from real user comparisons. Users compare two anonymous responses and choose their preferred answer. The platform combines these votes using the Bradley-Terry rating system. Each model receives a score based on its battle results. Rankings also show confidence ranges around each score. More votes can make rankings more reliable over time.
Human Preference Voting
Arena uses votes from real users to compare AI model responses. Users see two anonymous answers and choose their preferred response. Their choices become data for the model ranking system. The platform keeps model names hidden during voting to reduce bias. More votes help make rankings more reliable over time.
Arena Scores and Leaderboards
Each model receives a score based on its battle results. The leaderboard shows each model’s rank, score, and vote count. It also shows a rank spread and confidence range. Rankings update as users submit more comparisons. Different leaderboards cover text, coding, vision, search, and other tasks.
Best AI Models on LMArena in 2026
Arena’s leaderboards include many models from leading AI companies. Rankings can change as new models enter the platform. Different categories also produce different results. The platform ranks models across text, coding, vision, image generation, and agent tasks. For this reason, users should check the latest leaderboard before choosing a model.
Top Models for General Text
As of September 2026, Arena’s text leaderboard includes over 400 models. The leading models include Claude Fable 5 High and Claude Opus 4.6 High. Claude Opus 4.7 High and Muse Spark 1.2 also rank highly. Gemini 3.8 Flash High is another model near the top. Rankings can change as users submit new votes.
Top Models for Coding and Reasoning
Arena’s coding leaderboard compares models on real web development tasks. As of September 2026, GPT-6 Astra Max ranks first in WebDev Arena.
Claude Fable 5.1 Max and Claude Opus 5 Max follow closely. Qwen3.8 Max and Kimi K3 Max also rank among the leaders. These tests include coding, tool use, and multi-step reasoning tasks. Rankings can change as new models enter and users submit votes.
LMArena AI vs ChatGPT, Claude, and Gemini
LMArena, now called Arena, does not compete with ChatGPT, Claude, or Gemini. Instead, it lets users compare responses from different AI models. ChatGPT comes from OpenAI, while Claude comes from Anthropic. Gemini comes from Google and supports several AI tasks and formats. Arena compares these models through real user preferences and voting. Its leaderboards cover text, coding, vision, search, documents, and agents. This makes Arena useful when comparing models for specific tasks. Rankings can change as new models enter and receive more votes.
Comparing AI Models by Use Case
Different AI models work better for different types of tasks. Arena provides rankings for several specific AI uses. These include text, coding, vision, documents, search, and image generation. It also covers video and agent-based tasks. Users can compare models based on the task they need. Coding rankings focus on performance across coding-related tasks. Document rankings measure document analysis and long-content reasoning. Search rankings evaluate web information retrieval and synthesis. This approach helps users choose models for specific needs.
LMArena AI Features and Capabilities
Arena offers several tools for comparing AI models across different tasks. Users can compare text, coding, vision, documents, search, and images. It also supports image editing, video generation, and agent tasks. Users can upload files and give models extra context. Arena also provides leaderboards based on real user comparisons. These rankings help users compare model performance across specific tasks. Arena now covers many AI capabilities beyond its original language focus.
Text, Coding, Vision, and Other AI Arenas
Arena covers several AI tasks beyond standard text comparisons. Its main arenas include text, coding, vision, and document analysis. Users can also compare models for image generation and image editing. Other arenas cover areas such as search, video, and AI agents. Each arena focuses on a specific type of AI task. This helps users compare models based on real-world performance. Arena updates its rankings as users submit more comparisons.
Side-by-Side Model Comparison
Arena lets users compare selected AI models side by side with the same prompt. You can choose specific models instead of using anonymous matchups. Each model generates its own response to your prompt. You can then compare the answers and judge their differences. This makes it easier to compare writing, coding, reasoning, and other tasks. Side-by-Side votes do not affect Arena’s public leaderboard rankings. Arena still collects these prompts and votes for research purposes. This feature helps users understand how different models handle similar requests.
Why LMArena AI Is Useful for AI Model Comparison
Arena helps users compare AI models using real-world prompts and human feedback. Users can compare responses instead of relying only on fixed benchmarks. Its leaderboards cover different tasks, including text, coding, vision, and search. This helps users see how models perform across different types of work. Arena also updates rankings as users submit more comparisons. In 2026, Arena added factuality rankings for Text and Search Arenas. These rankings combine human preferences with factual accuracy measures.
Human Feedback vs Traditional Benchmarks
Traditional benchmarks test AI models using fixed datasets and specific questions. Arena uses real user comparisons to measure model preferences. Users judge which response better matches their needs. This captures useful feedback from real-world conversations and tasks. However, human feedback does not measure every part of model quality. Arena now also measures factual accuracy in its Text and Search Arenas. This combines human preferences with factuality for a broader evaluation.
How to Use LMArena AI
To use Arena, open the website and enter your prompt. Choose the arena that matches your task. In Battle Mode, two anonymous models answer your prompt. Compare both responses and select the answer you prefer. After voting, Arena reveals which models generated each response. You can then continue chatting or start another comparison. You can also explore leaderboards for different tasks and model types.
Compare Models and Explore Rankings
Arena lets you compare AI models and explore their rankings in one place. You can open different leaderboards for specific AI tasks. These include text, coding, vision, documents, search, and image generation. Each leaderboard shows model ranks, scores, votes, and confidence ranges. You can also use filters for specific tasks or professional areas. Rankings update as users submit more comparisons and votes. This helps you understand model performance across different real-world tasks.
Limitations of LMArena AI
Arena rankings depend heavily on human preferences and real user comparisons. Different users may prefer different styles or types of answers. Rankings also change as new comparisons and models enter the platform. A higher ranking does not mean a model wins every task. Arena provides separate rankings for different tasks and categories. Some rankings also include confidence ranges around model scores. Arena now adds factuality measures to Text and Search rankings. These measures help, but no single ranking shows every part of quality.
Understanding AI Benchmark Results
AI benchmark results show how models perform under specific testing methods. Arena uses real user comparisons to measure model preferences. A higher score means users preferred that model more often. However, the score does not show every part of model quality. Arena also shows confidence ranges around model scores. These ranges show how much uncertainty exists around each score. Arena now includes factuality rankings for Text and Search Arenas. These rankings combine human preferences with factual accuracy. So, users should check the score, votes, and ranking spread together. This gives a clearer view of what the results actually mean.
LMArena AI FAQs
LMArena AI is now called Arena after its January 2026 rebrand. It compares AI models through real user feedback and voting. In Battle Mode, users compare two anonymous model responses. They vote for the response they prefer. The model names appear after users submit their votes. These anonymous votes help shape Arena’s public leaderboards. Arena also offers Side-by-Side comparisons with selected models. These votes do not affect the public leaderboard rankings. Arena covers text, coding, vision, documents, search, images, and agents. Its rankings update as users submit more comparisons.
Final Thoughts on LMArena AI
LMArena, now called Arena, offers a practical way to compare AI models. It uses real user feedback instead of relying only on fixed benchmarks. Users can compare models across text, coding, vision, documents, and other tasks. Arena also adds factuality measures for its Text and Search rankings. Its leaderboards update as users submit more comparisons and votes. This makes the rankings useful for understanding current model performance. However, rankings should always be viewed within their specific task. Different models can perform differently across different AI tasks.
Disclaimer:
This article provides general information about Arena and AI model rankings. Rankings and model availability can change over time. Always check the official Arena website for the latest information.